Home / Writing
Building systems. Staying rigorous.
Plain, practical notes on multi-agent orchestration, document retrieval pipelines, and knowledge graphs. Built from real production architectures.
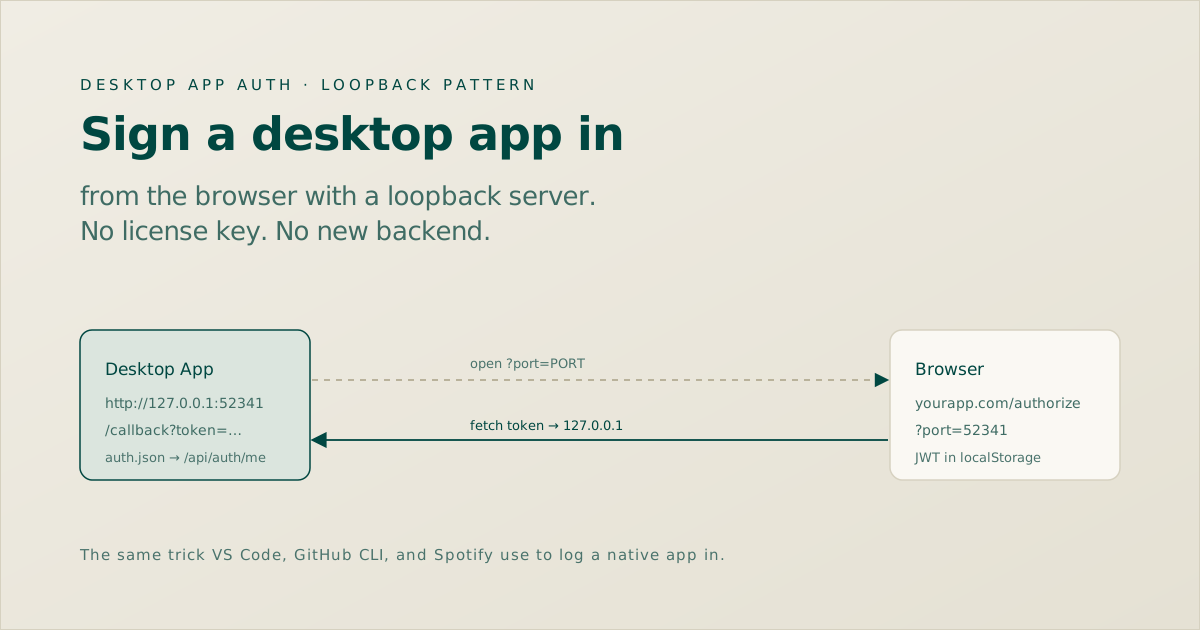
Kill the license key: sign a desktop app in from the browser
Copy-paste license keys are a support tax. The browser already holds a valid session token, so let it hand that token to the app over a loopback server. The same pattern VS Code, GitHub CLI, and Spotify use, with zero new backend endpoints.
Context Rot: why long-running agents get dumber the longer they run
Agents do not fail because the context window is too small. They fail because everything gets stuffed into it. On tool output bloat, lossy compaction, sub-agent isolation, and the four-tier memory hierarchy that keeps a sixty-step task on the rails.
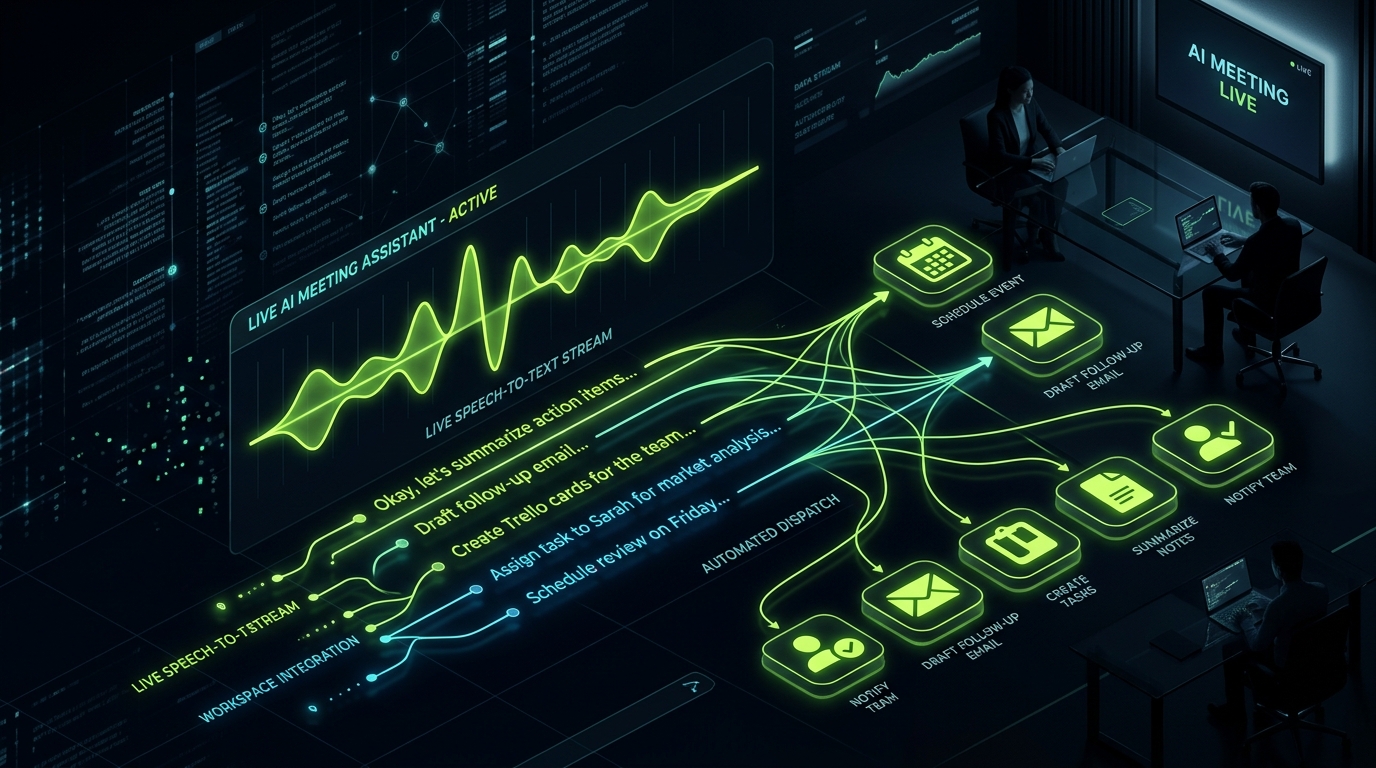
The AI Meeting Assistant Playbook: Market Growth, Technology Stacks, & Multi-Connector Architecture
An in-depth breakdown of the $2.5B+ meeting intelligence market, how leaders like Granola, Otter, Wispr Flow, and Plaud operate under the hood, hardware vs software audio capture, and building multi-connector sync systems.
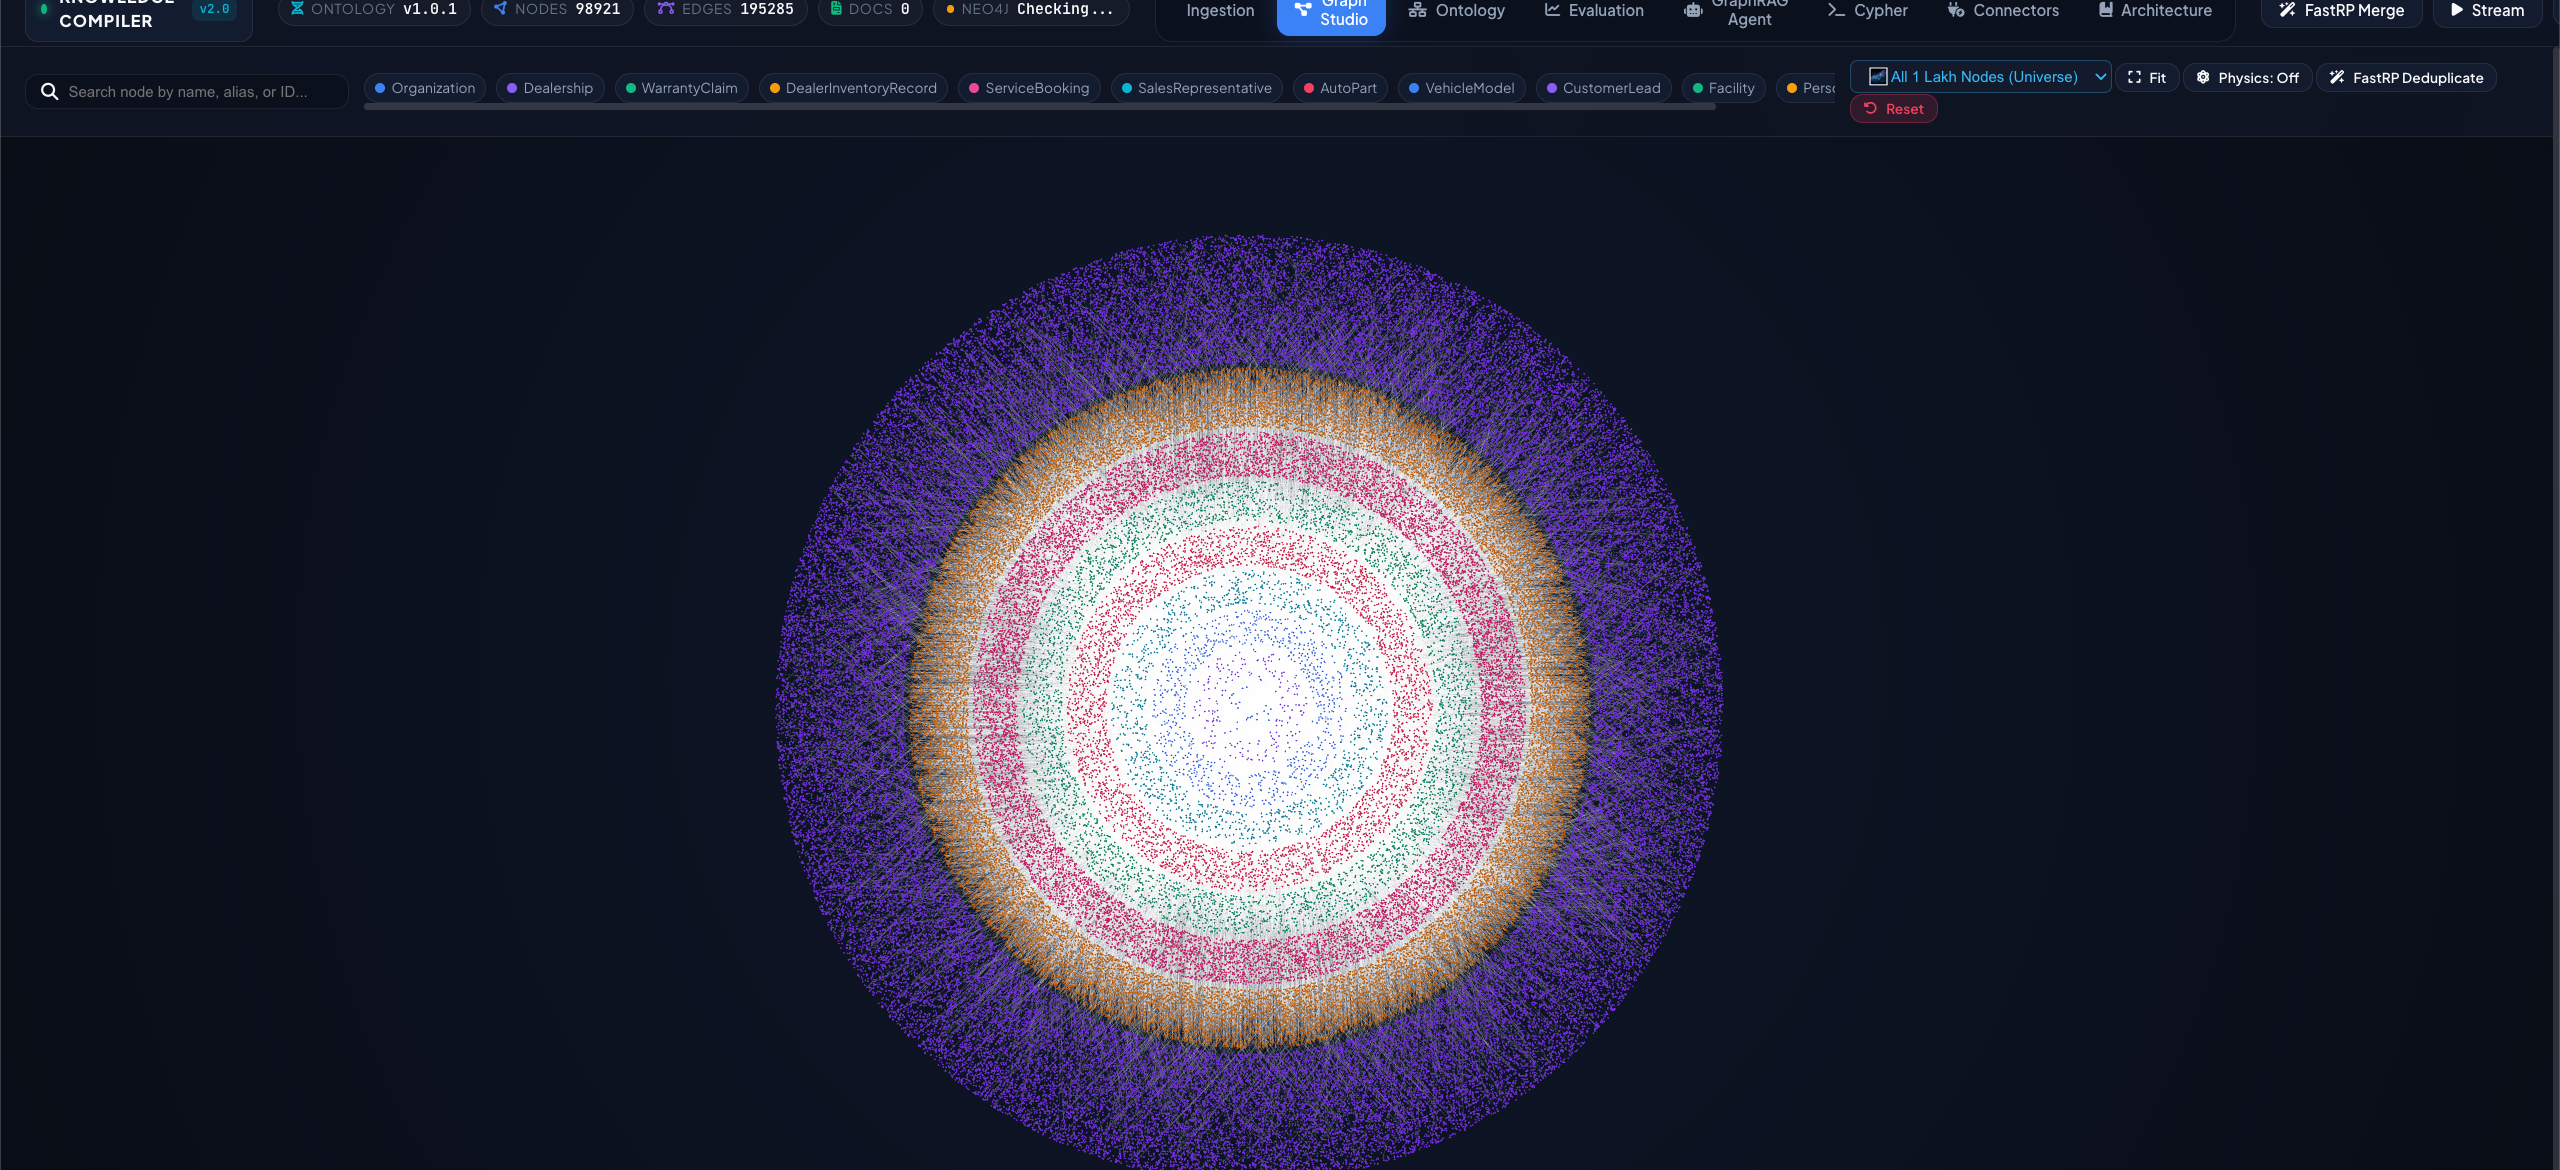
Compiling Enterprise Data into a 100k+ Node Context Graph
From AST chunking and bitemporal patches to FastRP topological deduplication and grounded GraphRAG agent traversal at 100,000-node scale.
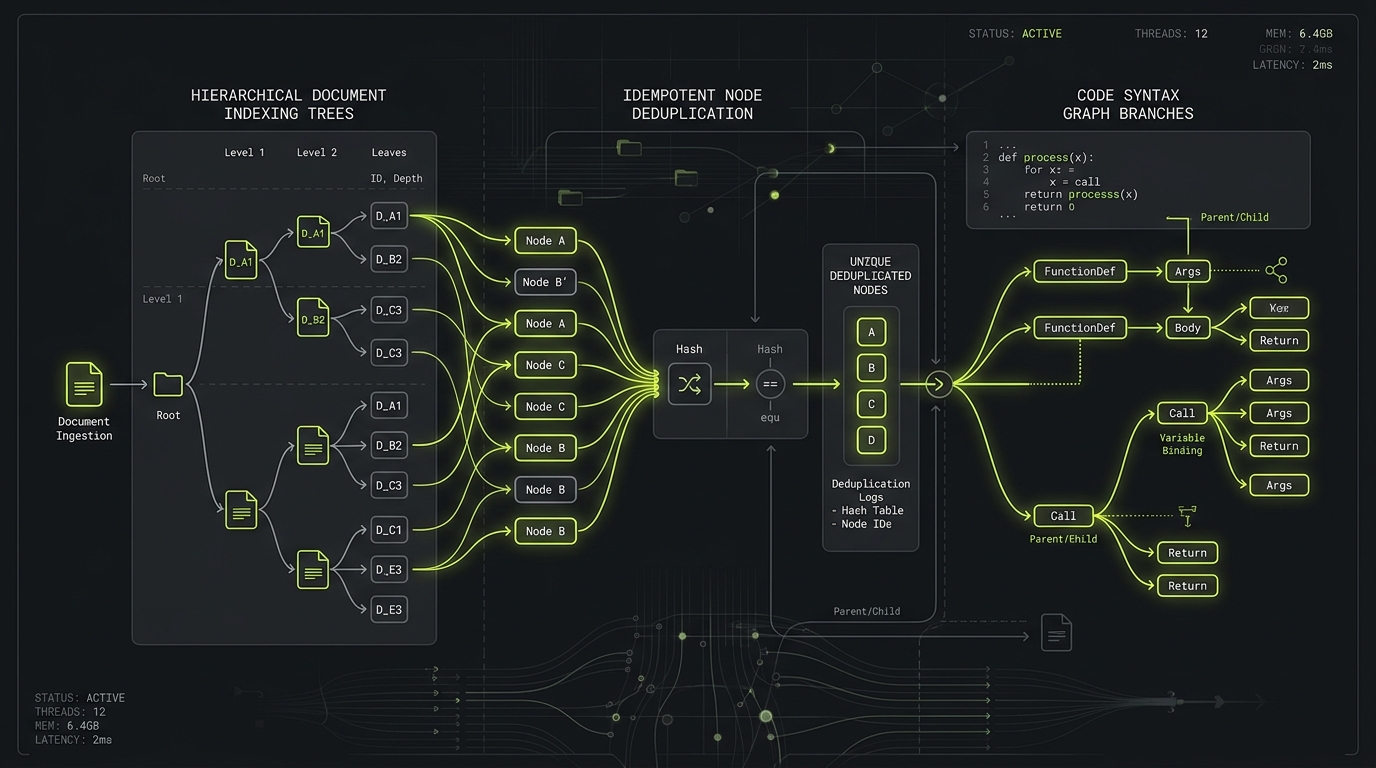
Making Document Indexing Idempotent & Incremental
A deep dive into PageIndex PR #314 and PR #383: eliminating duplicate UUIDs, preventing vector drift, and designing node-level versioning with deferred summary regeneration for the 34k★ repo.
Why Naive RAG Fails on Financial Documents
VC pitch decks often conflict with actual SEC filings. I built ClaimCheck to catch those conflicts automatically. Here is why standard chunked RAG broke down, and how tree-based parsing solved it.